Monorepo vs Polyrepo: The Stack Choice That Sticks
Summary
For most solo devs building a product with shared packages, a monorepo is the right default in 2026. This guide explains what you actually gain beyond the textbook pitch, when polyrepo genuinely wins, what CI/CD costs to expect, and how AI coding tools like Cursor and Claude Code shifted the classic tradeoffs. Plus three concrete signals that tell you it's time to split into separate repos.
The monorepo vs polyrepo question comes up before every new project, and the answer shapes months of CI/CD setup, refactoring overhead, and team access control. For most solo devs building a product with shared code, the right default in 2026 is monorepo. Not because it's the trendy choice, but because it removes the publishing ceremony that polyrepos impose the moment two packages need to talk to each other. If your services are fully independent and will genuinely never share code, polyrepo is simpler. Every other case is context.
It's 22h. You've got a new project taking shape: a backend API, a package of shared TypeScript types, and a frontend dashboard that will inevitably consume both. Two tabs open. The cursor is blinking.
Most posts on this topic are written for engineering teams of twenty with a dedicated DevOps engineer who enjoys configuring Bazel. This one is for builders who need to make the call before the first commit, because restructuring six months in, when you have real users and a CI pipeline your muscle memory has memorized, is the kind of thing that kills a side project's momentum for good.
What a monorepo actually buys you (not the textbook version)
The standard pitch is "one repo, shared dependencies, atomic changes." That's all real. But the part that actually matters day-to-day for a solo builder is more concrete: you don't have to publish packages to use them locally.
In a polyrepo setup, if shared-utils needs a fix that also affects api-service, you either publish a new version of shared-utils, bump the dependency in api-service, wait for CI to pass, and then deploy. Otherwise you fall back on npm link hacks that work until they stop working mid-sprint. In a monorepo with workspaces, you change the code, and every package that imports it sees the change immediately. No publishing ceremony.
Here's what that looks like with pnpm workspaces, which adds minimal configuration overhead:
/packages
  /shared-types      ← imported directly by api and web
  /api
  /web
package.json         ← workspace root with "workspaces" field
// api/package.json
{
"dependencies": {
"@myapp/shared-types": "workspace:*"
}
}No publishing. No version bumping during development. workspace:* resolves to the local package, and TypeScript's project references give you incremental compilation across the whole graph.
The second real benefit: cross-package refactoring that lands in one PR. Rename an interface in shared-types? TypeScript tells you every consumer that broke, in the same codebase, in the same editor session. In a polyrepo, you rename it in repo A, publish a new version, and discover the breakage in repo B three days later when a colleague runs npm install and the types don't match the runtime anymore.
The third benefit, which solo devs underestimate: one place for tooling configuration. One .eslintrc, one prettier.config.js, one CI workflow file. Small savings per change, but they compound over months of iteration.
It's worth naming what a monorepo does not give you: it does not make services less coupled. If your services are genuinely independent and you put them in a monorepo anyway, you've added coordination overhead without a return on it. The monorepo's benefits materialize only when the services actually share code or need to change together. The repo structure should reflect the dependency structure, not impose one.
When polyrepo earns its place
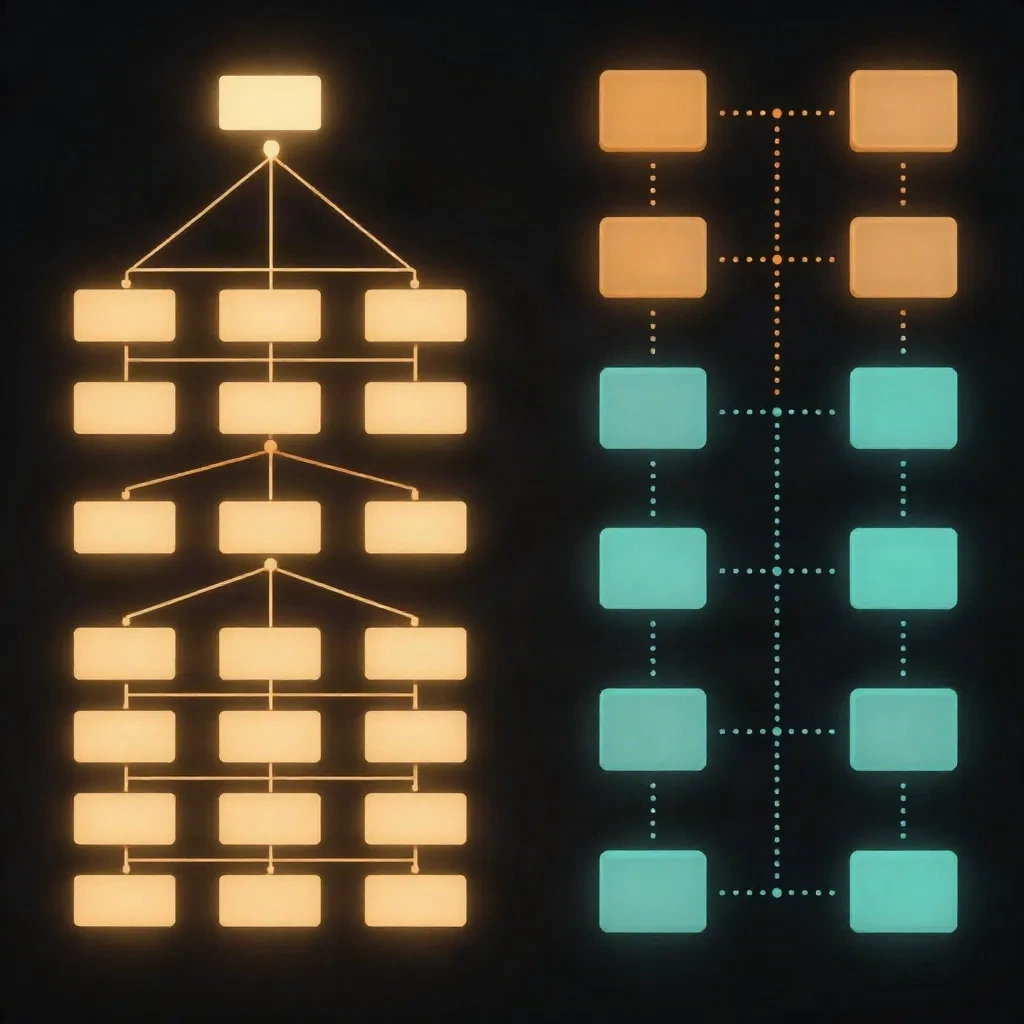
Polyrepo is not a mistake. It's the right choice for specific situations, and pretending otherwise is how you end up with a 40-service monorepo that takes 25 minutes to clone.
The clearest case: services with genuinely different ownership, release cycles, or compliance requirements. If your billing service is PCI-scoped and your marketing site is not, keeping them in separate repositories means keeping access control, audit logs, and blast radius cleanly separated. That's not operational overhead. That's the feature.
Polyrepo also wins when you're open-sourcing part of your codebase. A dedicated public repo lets external contributors fork and PR without pulling your private infrastructure into scope. GitHub's repository-level permission model doesn't give you clean path-based access isolation at scale. A separate repo handles that correctly.
And for pure microservices with completely distinct tech stacks: a Go service and a React Native app that literally share nothing at the code level, a monorepo adds coordination cost without delivering the benefit. If there are no shared packages, there's nothing to share.
The honest version of this: most indie projects that start with a polyrepo end up regretting it, not because polyrepo is bad architecture, but because they overestimated how independent the parts would stay. The frontend always ends up needing a type from the backend. The worker always ends up needing a utility from the API. Two repos become four PRs for every feature.
The CI/CD cost that nobody mentions until it hits your bill
Monorepos have a real operational cost: if your CI naively runs everything on every commit, you're paying in time and money for builds and tests that have nothing to do with what you changed.
Push a CSS tweak to the web package. CI runs the full test suite for api, worker, and shared-types. That's six minutes of GitHub Actions compute for a color change. At scale, this turns into CI queues that block your whole team.
The solution exists, but it requires deliberate setup: build orchestration tools that understand your dependency graph. Turborepo and Nx both solve this. Turborepo's turbo.json defines a pipeline where each task runs only for packages with changed inputs:
{
  "pipeline": {
    "build": {
      "dependsOn": ["^build"],
      "outputs": ["dist/**"]
    },
    "test": {
      "dependsOn": ["build"],
      "cache": true
    }
  }
}
With remote caching enabled (free on Vercel's Turborepo Cloud tier for small teams), a cache hit on an unchanged package is instant, no rebuild, no retest. For a solo dev on a side project, this keeps CI under two minutes on most pushes once the build artifacts are warm.
The cost: you need to learn Turborepo or Nx before you need it, not after. It's roughly half a day of setup. If you skip it and let CI accumulate fat, monorepo CI will slow to the point where you start questioning the whole architectural choice, and that's usually when developers decide polyrepo was right all along, when the real problem was just a missing config file.
How AI coding tools changed the math on this debate
Until recently, one genuine argument for polyrepo was cognitive load: smaller repos are easier to reason about because they're isolated. Context-switch to a new service, see only what's relevant for that service. The argument was legit.
AI coding tools shift that calculation. When you're working with Cursor, Claude Code, or GitHub Copilot, the tool works with your full codebase in context. It sees cross-service dependencies, understands which interface is consumed by which service, and can track a renamed field through every consumer without you holding the mental model yourself. The "isolated repo is easier to understand" argument weakens significantly when your AI assistant holds the whole dependency graph in context anyway.
A concrete example: in a polyrepo setup, if you ask an AI assistant to refactor an API endpoint that also affects a shared type, it typically can't see both repos in one session. You're doing the coordination manually, which is exactly the overhead a monorepo was supposed to eliminate. In a monorepo, the same refactor is one conversation.
This doesn't flip the decision entirely. But it removes one of the historical justifications for polyrepo for small teams and solo devs, and tips the default slightly further toward monorepo when the code is genuinely coupled.
Three signals that mean you should split the repo now
You started with a monorepo. Good. But here are the concrete signals that the split has become the right call:
Access control is becoming load-bearing. A contractor needs frontend access, not backend. A partner integration team needs to read your API schema but nothing proprietary. GitHub's Codeowners can restrict who can review which paths, but it doesn't restrict read access. If read isolation matters for compliance or security, separate repos are the clean answer. Codeowners gymnastics never fully replaces repository-level permissions.
CI failures in one service are blocking deployment in an unrelated one. If a broken test in payment-service is gating a hotfix you need to ship in marketing-site, your monorepo is creating coupling that your codebase doesn't have. Either the build configuration needs fixing (task scoping with Turborepo will solve this), or the two services genuinely don't belong in the same repo.
One part is going open-source and one isn't. This is the cleanest split case. Extract the open-source piece into its own public repo. Mixed public/private code in a GitHub monorepo is genuinely painful: you'd need a separate organization or a manual pruning process that creates permanent maintenance overhead.
The practical setup most builders land on
The answer most experienced developers settle on: one monorepo per product domain, not "one monorepo for everything you've ever built" and not "one repo per package."
If you're building a SaaS with a web frontend, an API, and a shared type library, that's one product. Keep it in one monorepo. If you also maintain an open-source CLI utility that other projects use, that's a different repo with a different audience and release cycle.
The mistake is treating the monorepo/polyrepo choice as ideological. It's not "monorepo teams" versus "polyrepo teams." It's a structural decision based on three questions: What is the dependency graph between your services? Who needs access to what, and does isolation matter? What is your tolerance for CI/CD setup complexity?
For side projects specifically: start with a monorepo using pnpm workspaces (npm workspaces work too, just less ergonomic). Add Turborepo only when your CI starts regularly hitting 4+ minutes. Split into a separate repo only when you have a concrete reason: open-source, access control, compliance, or a partner team with different release cadence. Not because it feels architecturally cleaner.
The monorepo vs polyrepo debate is one of those choices where the right answer for most solo devs is the same: start simple, optimize when the specific friction appears. The cursor is still blinking. Ship the first commit.